AI compute platform

Built on DEEPX and SiMa.ai silicon

A co-designed hardware and software stack. Two families of purpose-built edge AI processors carry the inference workload — letting a single appliance analyse many channels at a fraction of the power a GPU server would draw.

Physical AI semiconductors

DEEPX

Chips, M.2 modules, PCIe accelerator cards and complete edge AI systems for high-density video inference.

ProductPerf.Power
DX-M1 chip / M.225 TOPS1–5 W
DX-M1M chip / M.225 TOPS3 W
DX-H1 Quattro PCIe100 TOPS20 W
DX-H1 V-NPU + codec50 TOPS30 W
DX-AIPlayer edge box25 TOPS15–37 W
DX-M2 2 nm, edge LLM80 TOPS~5 W
  • IQ8 INT8 · near-FP32
  • DXNN SDK
  • 64-ch H.264/265 decode
  • −40 to 85 °C
  • Chip · M.2 · PCIe · Box

MLSoC for physical AI

SiMa.ai Modalix

One heterogeneous chip runs the entire multimodal pipeline — 50 TOPS under 10 W, no glue silicon or external accelerators.

ProductPerf.Power
Modalix SoM, Jetson-compat.50 TOPS<10 W
Modalix HHHL PCIe Gen550 TOPS<10 W
Modalix MLSoC chip-down50 TOPS<10 W
Modalix DevKit platform50 TOPS<10 W
  • BF16 / INT8 / INT16
  • Palette Neat SDK
  • CNN · ViT · LLM · LMM
  • MIPI · USB · PCIe Gen5
  • TrustZone security
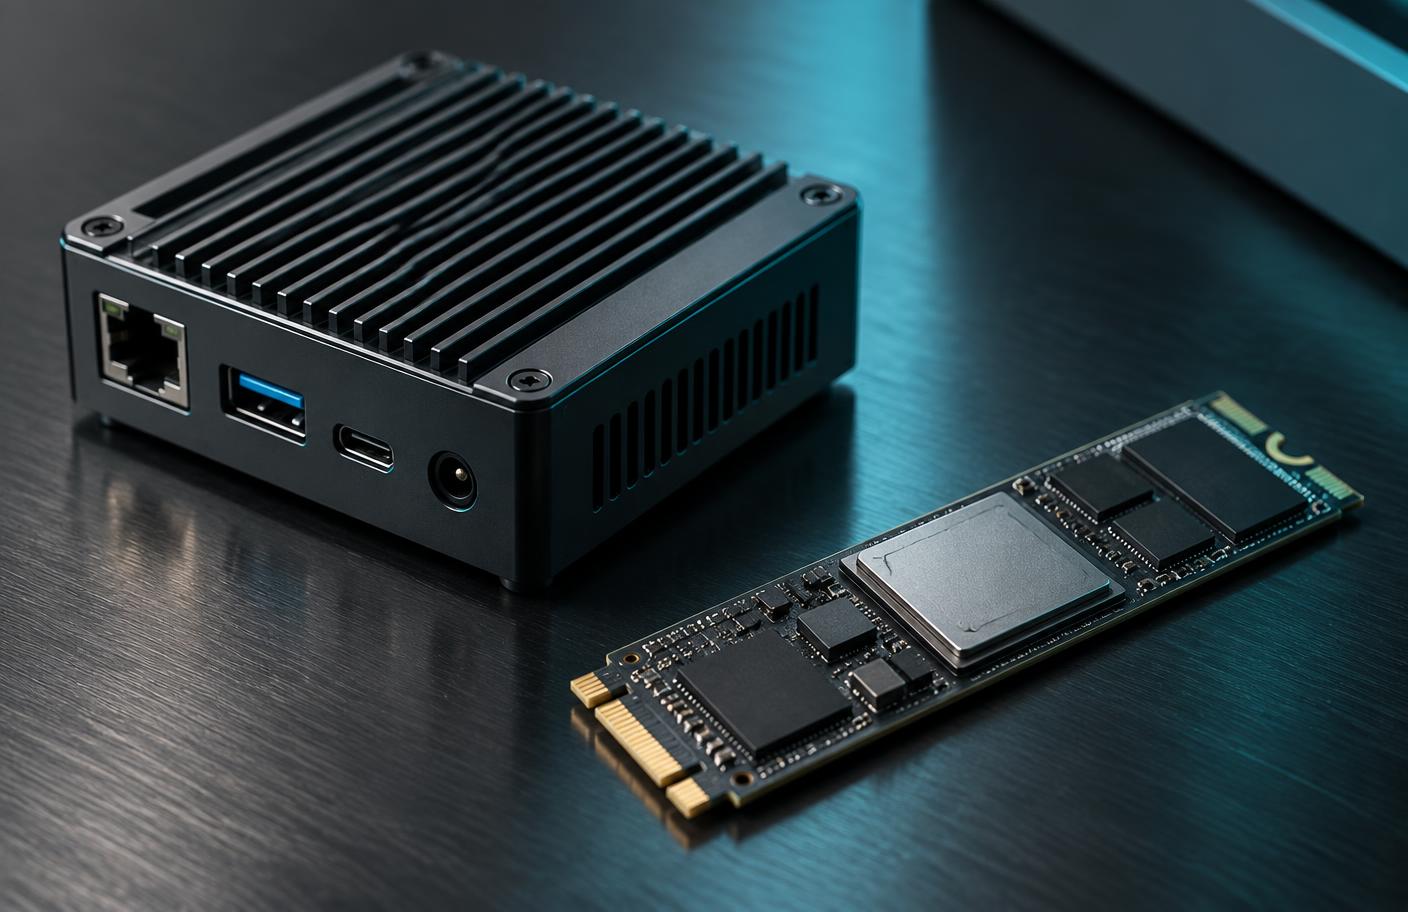
Edge AI accelerator module and M.2 NPU card used in VisionX deployments
Accelerator line-up deployed in VisionX — M.2 NPU modules, PCIe cards and compact edge appliances.

One software layer. Two silicon paths. Zero lock-in.

VisionX abstracts both accelerator families behind a single model runtime and rule engine. Scale from a compact DEEPX camera to a SiMa.ai Modalix appliance — without changing the operator interface, event schema or integration APIs.

Modalix advantage

Accelerates the entire LMM pipeline on one chip — sensor capture, preprocessing, vision encoder, LMM and app logic.

Custom models

Standard ONNX / PyTorch / TensorFlow converts to optimized .dxnn or .sima NPU binaries in hours.

Deployment enquiry

See VisionX analyse your own camera streams

Book a live demo, request a dev kit or size a deployment with our engineering team.